- 联系我们
- duidaima.com 版权声明
- 闽ICP备2020021581号
-
 闽公网安备 35020302035485号
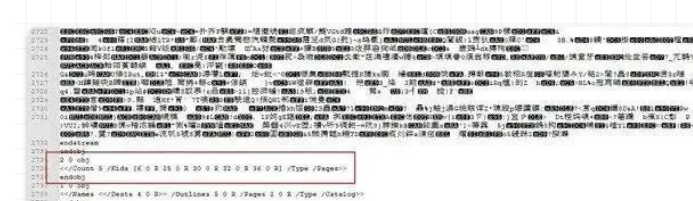
 1 0 obj % 1 为对象编号,0 为对象版本号
 <<  >>
 endobj
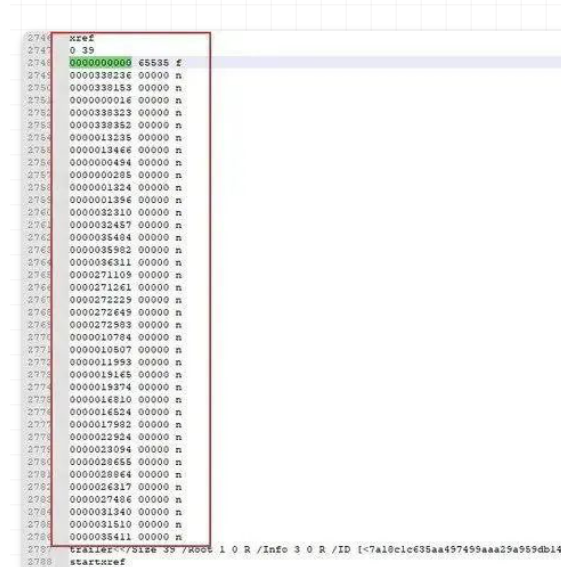
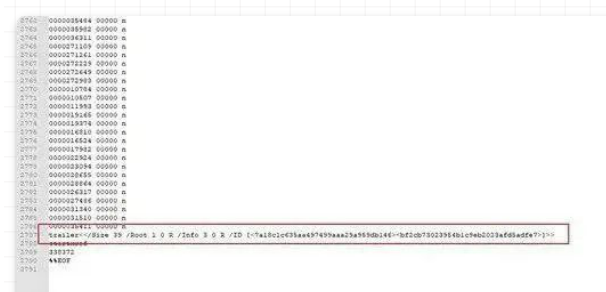
Xref(交叉引用表)
 12 0 obj
 <<  >>
 stream
 % 流数据
 endstream
 endobj
PDF Parser
 const getBufferView = (file: File) => {
   return new Promise<Uint8Array>((resolve, reject) => {
     const reader = new FileReader();

     reader.onload = () => {
       resolve(new Uint8Array(reader.result as ArrayBuffer));
     };

     reader.onerror = reject;

     reader.readAsArrayBuffer(file);
   });
 };
这里我们将文件读取后转换为了 Uint8Array 实例,之所以选择它,是因为 PDF 中可读数据都存在于 ASCII 码表中,而 8 位二进制所能表示的最大值是 255,足以表示 ASCII 码表中的所有数据。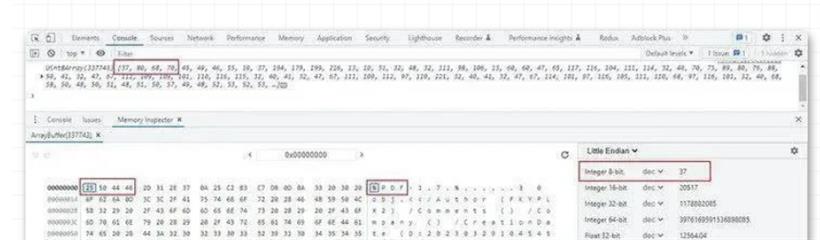
 const isTypeOf =
   (binary: number[]) => (maybe: Uint8Array, offset?: number) =>
     binary.every((correct, i) => correct === maybe[i + (offset || 0)]);
这个工具函数接收一个字节标识,返回一个对比函数,对比函数通过对字节标识的按位对比来判断数据是否相等,需要注意的是对比函数还支持一个可选的字节偏移,指示应从数据的哪个位置开始对比。这个函数的使用如下: const Flag = {
/** pdf magic number */
IS_PDF: [0x25, 0x50, 0x44, 0x46]
};
const isPDF = isTypeOf(Flag.IS_PDF);
isPDF(uint8); // PDF 的 magic number 位于文件的头部,偏移为 0,可以不用指定偏移数
数据类型解析 /** 堆代码 duidaima.com */
/** 将 Uint8Array 解码为可读文本 */
const toText = (binary: Uint8Array) => new TextDecoder().decode(binary);
class PDFParser {
/** 被处理的文件数据 */
bytes: Uint8Array;
/** 字节偏移 */
offset = 0;
/** 缓存字节偏移,当解析不成功时回退偏移 */
beforeOffset = 0;
/** 数组解析深度 */
depth = 0;
/** 状态栈 */
stateStack: PDF.StateStack = [];
constructor(bytes: Uint8Array) {
/** 文件数据 */
this.bytes = bytes;
}
/** 字节偏移前进控制 */
forward(step?: number) {
return isNumber(step) ? (this.offset += step) : ++this.offset;
}
/** 字节偏移后退控制 */
back(step?: number) {
return isNumber(step) ? (this.offset -= step) : --this.offset;
}
/** 字节偏移设置 */
set(before: number) {
return (this.offset = before);
}
/** 缓存当前字节偏移 */
cache() {
this.beforeOffset = this.offset;
}
/** 回退字节偏移 */
reset() {
this.offset = this.beforeOffset;
}
/** 解析值 */
parseValue(stream: Uint8Array, decision?: ReturnType<typeof isTypeOf>) {
/** 数据开始 */
let startOffset = this.offset;
const isBreak = (bytes: Uint8Array, offset?: number) =>
decision
? !decision(bytes, offset)
: !isBreakPoint(bytes, offset) &&
!isEnd(bytes, offset) &&
!isStart(bytes, offset);
for (; ; this.forward()) {
/** 不为断点则视为数据开始 */
if (isBreakPoint(stream, this.offset)) continue;
/** 开始偏移 */
startOffset = this.offset;
for (; ; this.forward()) {
/** 为断点处或为特征数据结尾则视为数据结束 */
if (isBreak(stream, this.offset)) continue;
return stream.slice(startOffset, this.offset);
}
}
}
/** 解析数字 */
parseNumber(stream: Uint8Array) {
/** 缓存偏移 */
this.cache();
/** 解析值请判断是否为数字 */
const num = window.parseFloat(toText(this.parseValue(stream)));
if (!isNumber(num)) {
/** 不为数字则回退偏移 */
this.reset();
return false;
}
/** 否则返回数字 */
return num;
}
/** 解析引用:1 0 R */
parseQuote(stream: Uint8Array) {
/** 解析数字 */
const serial = this.parseNumber(stream);
/** 不为数字说明不是间接引用 */
if (!isNumber(serial)) return false;
/** 缓存偏移 */
this.cache();
/** 是否为数字,且后跟 R 标识 */
const version = window.parseFloat(toText(this.parseValue(stream)));
const isQuoteFlag = isQuote(this.parseValue(stream));
/** 不为数字或不存在 R 标识则回退偏移,并返回第一个数字 */
if (!isNumber(version) || !isQuoteFlag) {
this.reset();
return serial;
}
/** 返回间接引用 */
return { type: 'quote', serial, version } as const;
}
/** 解析数组 */
parseMultivalued(stream: Uint8Array) {
const values: unknown[] = [];
let value: unknown = undefined;
/** 解析引用或数字 */
const addQuote = () => {
value = this.parseQuote(stream);
value !== false && values.push(value);
};
/** 默认执行一次 */
addQuote();
/** 不为数组结束符号 ] 时执行循环体 */
while (!isSquareBracketEnd(stream, this.offset)) {
switch (true) {
/** 解析字典 */
case isDictionaryStart(stream, this.offset):
values.push(this.parseDictionary(stream));
break;
/** 解析数组 */
case isSquareBracketStart(stream, this.offset):
this.forward(Feature.SQUARE_BRACKET_START.length);
/** 解析深度加 一 */
this.depth++;
values.push(this.parseMultivalued(stream));
break;
/** 解析名称 */
case isInclined(stream, this.offset):
this.forward(Feature.INCLINED.length);
values.push({ type: 'name', value: toText(this.parseValue(stream)) });
break;
/** 解析字符串 */
case isArrowStart(stream, this.offset):
this.forward();
values.push(toText(this.parseValue(stream, isArrowEnd)));
break;
/** 解析字符串 */
case isParenthesesStart(stream, this.offset):
this.forward();
values.push(toText(this.parseValue(stream, isParenthesesEnd)));
break;
default:
this.forward();
addQuote();
break;
}
}
/** 递归解析数组, 如果解析深度不为 0, 则上层数组还需继续解析数组元素 */
if (this.depth !== 0) {
/** 字节偏移前进一位,避免上层数组解析到内部数组的 ] 符号而中止循环 */
this.forward(Feature.SQUARE_BRACKET_END.length);
this.depth--;
}
return values;
}
/** 解析字典 */
parseDictionary<T>(stream: Uint8Array): T {
/** 字典数据 */
const dictionary = {} as T;
/** 是否结束当前解析 */
let jumpOut = false;
/** 当前键 */
let key = '';
/** 顶部栈数据 */
const top = () => this.stateStack[this.stateStack.length - 1];
/** 状态栈弹出 */
const popStack = (key: PDF.StateStackKeys) => {
const topKey = this.stateStack.pop();
/** 顶部栈数据与当前数据不一致时,则解析出错 */
if (!isEqual(topKey, key)) {
throw Error(
'analyze the PDF error, please contact the plug -in developer'
);
}
};
/** jumpOut 在遇到字典结尾符号 >> 时会为 true,则停止循环解析 */
while (!jumpOut) {
switch (true) {
/** 字典开头 <<,字节为 [0x3c, 0x3c] */
case isDictionaryStart(stream, this.offset):
this.forward(Feature.DICTIONARY_START.length);
this.stateStack.push('DICTIONARY_START');
if (key !== '') {
// 递归字典解析
dictionary[key] = this.parseDictionary(this.bytes);
key = '';
}
break;
/** 字典结尾 >>,字节数据为 [0x3e, 0x3e] */
/** 可能是字符串与字典结尾 >>>,因此需要判断顶部栈是否是字典结尾 */
case isEqual(top(), 'DICTIONARY_START') &&
isDictionaryEnd(stream, this.offset):
this.forward(Feature.DICTIONARY_END.length);
popStack('DICTIONARY_START');
jumpOut = true;
break;
/** 数组开始 [,字节数据为 [0x5b] */
case isSquareBracketStart(stream, this.offset):
this.forward(Feature.SQUARE_BRACKET_START.length);
this.stateStack.push('SQUARE_BRACKET_START');
// 数组解析
dictionary[key] = this.parseMultivalued(stream);
key = '';
break;
/** 数组结束 ],字节数据为 [0x5d] */
case isSquareBracketEnd(stream, this.offset):
this.forward(Feature.SQUARE_BRACKET_END.length);
popStack('SQUARE_BRACKET_START');
break;
/** 名称 /,字节数据为 [0x2f] */
case isInclined(stream, this.offset):
this.forward(Feature.INCLINED.length);
/*
* 解析名称,需要注意的时,字典中的数据是两两成对的,键为名称,值也可以是名称,所以这里通过一个变量 key 缓存键,
* 当再次进入到当前代码块是判断 key 是否存在数据,存在则当前名称应作为值。
**/
if (key !== '' && key in dictionary && isUndef(dictionary[key])) {
dictionary[key] = {
type: 'name',
value: toText(this.parseValue(stream))
};
key = '';
} else {
key = toText(this.parseValue(stream));
/**
* 遇到名称时,如果这个名称没有被作为值使用,则会默认继续一次,如果解析的数据不为数字或引用,
* 则会回退字节偏移并继续循环解析。
*/
dictionary[key] = this.parseQuote(stream) || undefined;
}
break;
/** 16 进制字符串开始 <,字节数据为 [0x3c] */
case isArrowStart(stream, this.offset):
this.forward(Feature.ARROW_START.length);
this.stateStack.push('ARROW_START');
// 字符串解析
dictionary[key] = toText(this.parseValue(stream, isArrowEnd));
key = '';
break;
/** 16 进制字符串结束 >,字节数据为 [0x3e] */
case isArrowEnd(stream, this.offset):
this.forward(Feature.ARROW_END.length);
popStack('ARROW_START');
break;
/** 字符串开始 (,字节数据为 [0x28] */
case isParenthesesStart(stream, this.offset):
this.forward(Feature.PARENTHESES_START.length);
this.stateStack.push('PARENTHESES_START');
// 字符串解析
dictionary[key] = toText(this.parseValue(stream, isParenthesesEnd));
key = '';
break;
/** 字符串结束 ),字节数据为 [0x29] */
case isParenthesesEnd(stream, this.offset):
this.forward(Feature.PARENTHESES_END.length);
popStack('PARENTHESES_START');
break;
default:
/** 没有匹配时默认前进一位偏移 */
this.forward();
break;
}
}
/** 返回字典对象 */
return dictionary;
}
}
上述代码虽然多,但基本操作都是相同的,只是不断的前进字节偏移并对匹配的数据做处理,需要注意的只是对于字节偏移的管理。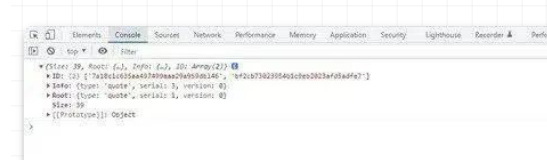
 getPdfXref(stream: Uint8Array) {
   // startxref 记录了交叉引用表所在的字节偏移
   /** 设置偏移为 startxref + xref 的长度 */
   this.set(this.startxref + Flag.XREF.length);

   /** 解析对象开始编号 */
   this.parseValue(stream);

   /** 解析对象个数 */
   let size = window.parseFloat(toText(this.parseValue(stream)));

   while (size--) {
     /** 解析对象偏移 */
     this.xref.push(window.parseFloat(toText(this.parseValue(stream))));

     /** 未知 */
     this.parseValue(stream);

     /** 标识 */
     this.parseValue(stream);
   }
 }
这里我们着重讲解下 parseValue 方法的作用,在 PDF 中,数据分割通常使用空格符、换行符来实现,parseValue 就是在不断的前进字节偏移中,找到不为分割符号的字节偏移,将其作为数据的开始,然后继续前进,当遇到分割符号时,将当前的字节偏移作用数据的结束,并将两个字节偏移中的数据切割出来。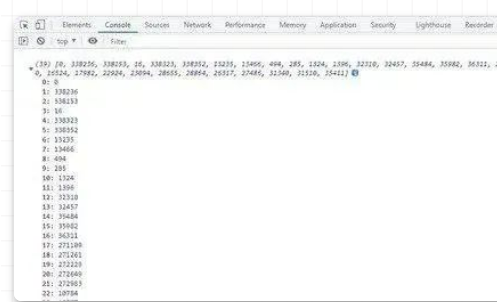
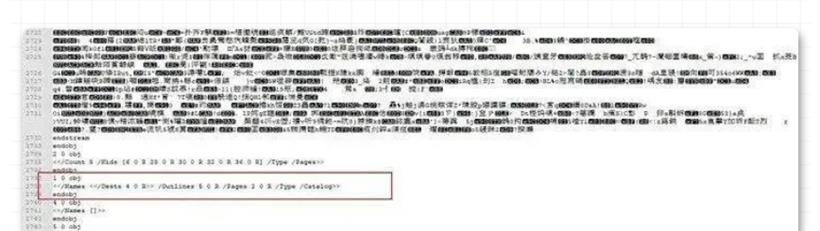
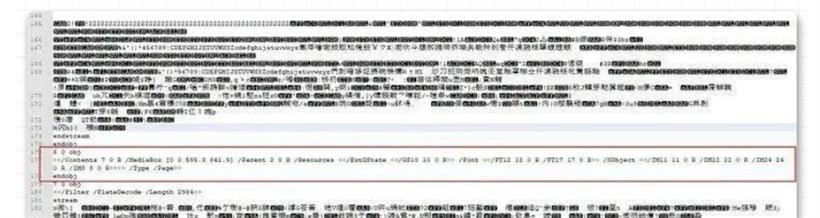
Resources:页面的资源,如图形状态、字体、图片等。